Tuesday, 6 November 2018

Ethereum

What is Ethereum?
  1. Just like the Bitcoin, Ethereum is decentralized — no one regulates or owns it — it has it’s own cryptocurrency or “fuel” called “Ether” which acts in the same way bitcoin does.
  2. However, Ethereum has a few innovations worth noting. It is the second application on its blockchain infrastructure called a “smart contract”, it’s own virtual machine which powers the memory and applications on the network called the “ethereum virtual Machine”, and it's own programmable language called “Solidity”.


Solves issues of Scaling or Privacy in public networks.

Smart Contracts: a piece of code deployed in a blockchain node and are Centerpiece of the Ethereum.

Execution of the smart contract is initiated by a message embedded in the blockchain transaction

Ethereum may carry out more sophisticated transactions than simple subtraction or addition transactions as we saw in bitcoin.

E.g.: conditional transfer
Some evaluations
More than one signature for transfer of assets
OR it may involve waiting for a specific day or time

  1. Smart contract code resembles the structure of OOP
  2. It has data, functions or methods with modifiers and structure
  3. Many languages have been designed for running Ethereum Smart Contracts
  4. SOLIDITY is one such language


EVM : Ethereum Virtual Machine

Bitcoin VS Ethereum


Ethereum introduced the concept of the account, as part of the protocol. Accounts are the basic units of the Ethereum protocol. The account is originator as well as the target of the transaction.
Ethereum involves a transfer of value, data or code.

EOA - Externally owned accounts
Controlled by private keys
EOAs are must needed to participate in the Ethereum Blockchain

They interact with the block chain using transactions.

Participant Node can send transaction for Ether transfer or to invoke smart contract or both
Both type of transactions require some fees
Sufficient fees should be present in account needed for the transaction which is activated
The fee is paid in Wei. Wei is a lower denomination of Ether.
1 ether = 10 ^18 Wei
Fees is paid in Wei


Fields in the transaction in Ethereum
  1. Recipient
  2. Digital Signature of sender authorizing transaction
  3. Amount of Wei to transfer
  4. Optional payload containing Message to a contract
  5. Start gas (maximum no. of computational steps  the transaction is allowed.)
  6. Gas price (fee for computations)


CA - Contract accounts
These are controlled by EOA. CA represents a smart contract. Every account has a coin balance.


Ethereum block structure has headers, transactions and runner-up block headers.

Monday, 1 October 2018

Workshop 1: Creating a Hyperledger Fabric network

Hyperledger Fabric Network

Creating a first hyperledger fabric network through Amazon AWS
  1. create an AWS account
  2. I created an AWS student account through www.awseducate.com
    Through your workbench, go to AWS console and create an EC2 instance
    Go to Services-> ec2-> launchinstance-> Ubuntu Server 16.04 LTS (HVM), SSD Volume Type-> m4large
    Add tag->basicnetwork, Create a new key-pair, Download key pair and click launch instance
  3. Connecting to the instance
  4. Once the instance has started, you can connect it through Putty
    Before connecting, convert the .pem file (key pair) into .ppk file using PuttyGen. This step is required because Putty requires a .ppk file and cannot connect using .pem file
    Now add .ppk file to Putty, and connect to the IP of the running AWS instance
  5. Creating first network - installing prerequisites
    1. Install cURL
    2. Type on the terminal cURL command to check if its installed or run cURL --version. If it is not installed you can install it through below command
      sudo apt-get install curl
    3. Install Docker and Docker Compose
    4. and
    5. Install GO Programming Language
    6. Don't forget to set the path. Run command export PATH=$PATH:$GOPATH/bin
    7. Install Node.js Runtime and NPM
    8. Install Python
    9. Retrieve the Python version 2.7, which is goof for running Fabric Node.js SDK, by using command sudo apt-get install python
      You can also check python version by command "python --version"
      You are essentially done for installing the prerequisites. You can refer to detailed installation article herehttps://hyperledger-fabric.readthedocs.io/en/latest/prereqs.html
  6. Installing Sample Binaries and Docker Images
  7. Once you are ready, and in the directory into which you will install the Fabric Samples and binaries, go ahead and execute the following command: curl -sSL http://bit.ly/2ysbOFE | bash -s 1.2.0
    then, curl -sSL http://bit.ly/2ysbOFE | bash -s curl -sSL http://bit.ly/2ysbOFE | bash -s 1.2.0 1.2.0 0.4.10
    I faced an issue of Docker permission denied while trying to connect to the Docker daemon socket
    I solved the issue with command sudo usermod -a -G docker $USER . Don't forget to completely log out of your account and log back in (if in doubt, reboot!):
  8. Running first network
  9. cd fabric-samples/first-network
    Ready to give it a go. Run the command: ./byfn.sh generate
    This command generates all the certificates. And after this, bring up the network
    ./byfn.sh up
    If you’d like to run through this tutorial with node chaincode, pass the following command instead:
    we use the -l flag to specify the chaincode language forgoing the -l flag will default to Golang
    ./byfn.sh up -l node
    Bring down the network with the command ./byfn.sh down

Hyperledger

What is Hyperledger?

https://blockgeeks.com/guides/what-is-hyperledger/
A lot of explanation on the above link.

Important to know -

  1. Hyperledger was created by Linux Corporation in late 2015. 
  2. It is not Bitcoin or some other crypto-currency. It is not Ethereum or some other code execution engine
  3. It aims to create an blockchain based environment where companies and developers can collaborate to create frameworks/ projects.
  4. More than 100 companies are part of it.
  5. What projects have been already created using it:


  • Hyperledger Sawtooth: This is a modular blockchain suite developed by Intel, which uses a new consensus algorithm called Proof of Elapsed Time (PoeT).


  • Hyperledger Iroha: Iroha is a project of a couple of Japanese companies to create an easy to incorporate the framework for a blockchain.


  • Hyperledger Fabric: This project is lead by IBM. Fabric is a plug and plays implementation of blockchain technology designed as a foundation to develop high-scaling blockchain applications with a flexible degree of permissions.

  • Simple video to understand Hyperledger fabric


    Hyperledger glossary
    https://hyperledger-fabric.readthedocs.io/en/release-1.2/glossary.html


    Tuesday, 25 September 2018

    UTXO: Unspent Transaction Output

    UTXO is geek-speak for “unspent transaction output.” Unspent transaction outputs are important because fully validating nodes use them to figure out whether or not transactions are valid– all inputs to a transaction must be in the UTXO database for it to be valid.

    From <https://www.google.com/search?q=UTXO&oq=UTXO+&aqs=chrome..69i57j0l5.3565j0j7&sourceid=chrome&ie=UTF-8>


    UTXO
    1. Unique identifier of the transaction
    2. Position of this UTXO in transaction output list
    3. Value or Amount
    4. Optional script

    Transaction contains
    1. Reference number of current transaction
    2. Reference to one or more input UTXO
    3. Reference to one or more output UTXO newly generated
    4. Total input amount and output amount

    Transaction hashes contain
    1. Hash of the current block
    2. Hash of previous block
    3. Hash of next block
    4. Merkle root hash of the block


    Double spending problem
    The risk that a digital currency can be spent twice. Double-spending is a potential problem unique to digital currencies because digital information can be reproduced relatively easily.


    Bitcoin solution
    We propose a solution to the double-spending problem using a peer-to-peer network. The network timestamps transactions by hashing them into an ongoing chain of hash-based proof-of-work, forming a record that cannot be changed without redoing the proof-of-work.


    The longest chain not only serves as proof of the sequence of events witnessed, but proof that it came from the largest pool of CPU power

    As long as a majority of CPU power is controlled by nodes that are not cooperating to attack the network, they'll generate the longest chain and outpace attackers.

    the chain stitches that data into encrypted blocks that can never be modified and scatters the pieces across a worldwide network of distributed computers or "nodes.

    From <https://www.pcmag.com/article/351486/blockchain-the-invisible-technology-thats-changing-the-wor>


    Basic operations: what Miners do?

    1. Validation of Transactions
    2. Gathering transactions for a block
    3. Broadcasting valid transactions and blocks
    4. Consensus of next block creation / acceptance
    5. Chaining blocks


    Transaction 0 Index  0 of the confirmed block
    1. Created by the miner of the block
    2. Does not have input UTXO
    3. Only has output UTXO (special UTXO)
    4. It generates Coinbase transaction (miner's fee)
    5. Miner fee - 12.5 BTC

    A standard transaction output can be unlocked with the private key associated with the receiving address. Addresses and their associated public/private key pairs will be covered later in the series. For now, we are concerned with the output amount only.

    From <https://www.ccn.com/bitcoin-transaction-really-works/>

    Sunday, 9 September 2018

    Blockchain basics

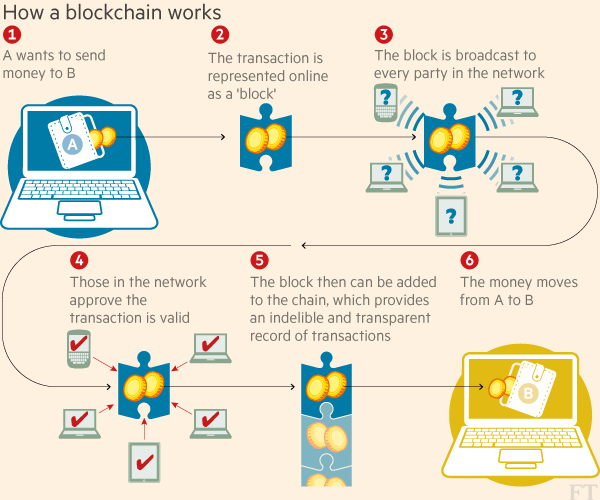
    → Blockchain is a decentralized, incorruptible digital ledger that can record transactions (like, but not limited to, financial transactions) directly among peers without having involvement of a third party or centralized system. 

    As an analogy, it can be thought of as a distributed database that maintains a shared list of records. These records are called blocks. Each encrypted block holds the history of blocks that came before it, with timestamped transaction data which chain the blocks together and hence termed as blockchain.

    The blockchain is also called public ledger because it is openly available for everyone to read.

    Its main characteristics are:

    1. Decentralized peer to peer network
    2. Establishing trust among unknown peers
    3. Recording the transaction in immutable, distributed ledger
    How is trust achieved?
    1. Validate, Verify and confirm transactions
    2. Record the transactions in a distributed ledger of blocks
    3. Create a tamper-proof chain of blocks
    4. Implement a consensus protocol for agreement on the block to be added in the chain


    Distributed Ledger

    In its simplest form, a distributed ledger is a database held and updated independently by each participant (or node) in a large network. The distribution is unique: records are not communicated to various nodes by a central authority but are instead independently constructed and held by every node. That is, every single node on the network processes every transaction, coming to its own conclusions and then voting on those conclusions to make certain the majority agree with the conclusions.
    Once there is this consensus, the distributed ledger has been updated, and all nodes maintain their own identical copy of the ledger. This architecture allows for a new dexterity as a system of record that goes beyond being a simple database.


    From <https://www.coindesk.com/information/what-is-a-distributed-ledger/

    Tuesday, 3 June 2014

    Java: JIT vs AOT

    JIT:    Just in Time Compiler
    AOT: Ahead of Time Compiler

    A JIT compiler can be faster because the machine code is being generated on the exact machine that it will also execute on. This means that the JIT has the best possible information available to it to emit optimized code.

    If you pre-compile bytecode into machine code as in AOT, the compiler cannot optimize for the target machine(s), only the build machine.


     Java must use a JIT
    The real killer for any AOT compiler is:
    Class.forName(...)
    This means that you cannot write a AOT compiler which covers ALL Java programs as there is information available only at runtime about the characteristics of the program. You can, however, do it on a subset of Java which is what I believe that gcj does.


    Another JIT advantage is to inline methods like getX() directly in the calling methods if it is found that it is safe to do so, and undoing it if appropriate, even if not explicitly helped by the programmer by telling that a method is final. The JIT can see that in the running program a given method is not overriden and is therefore in this instance can be treated as final.

    Java's JIT compiler is also lazy and adaptive.

    Lazy

    Being lazy it only compiles methods when it gets to them instead of compiling the whole program (very useful if you don't use part of a program). Class loading actually helps make the JIT faster by allowing it to ignore classes it hasn't come across yet.

    Adaptive

    Being adaptive it emits a quick and dirty version of the machine code first and then only goes back and does a through job if that method is used frequently.

    Well, I’ve heard it said that effectively you have two compilers in the Java world. You have the compiler to Java bytecode, and then you have your JIT, which basically recompiles everything specifically again. All of your scary optimizations are in the JIT.
    James: Exactly. These days we’re beating the really good C and C++ compilers pretty much always. When you go to the dynamic compiler, you get two advantages when the compiler’s running right at the last moment. One is you know exactly what chipset you’re running on. So many times when people are compiling a piece of C code, they have to compile it to run on kind of the generic x86 architecture. Almost none of the binaries you get are particularly well tuned for any of them. You download the latest copy of Mozilla,and it’ll run on pretty much any Intel architecture CPU. There’s pretty much one Linux binary. It’s pretty generic, and it’s compiled with GCC, which is not a very good C compiler.
    When HotSpot runs, it knows exactly what chipset you’re running on. It knows exactly how the cache works. It knows exactly how the memory hierarchy works. It knows exactly how all the pipeline interlocks work in the CPU. It knows what instruction set extensions this chip has got. It optimizes for precisely what machine you’re on. Then the other half of it is that it actually sees the application as it’s running. It’s able to have statistics that know which things are important. It’s able to inline things that a C compiler could never do. The kind of stuff that gets inlined in the Java world is pretty amazing. Then you tack onto that the way the storage management works with the modern garbage collectors. With a modern garbage collector, storage allocation is extremely fast.

    In theory, a JIT compiler has an advantage over AOT if it has enough time and computational resources available. For instance, if you have an enterprise app running for days and months on a multiprocessor server with plenty of RAM, the JIT compiler can produce better code than any AOT compiler.
    Now, if you have a desktop app, things like fast startup and initial response time (where AOT shines) become more important, plus the computer may not have sufficient resources for the most advanced optimizations.
    And if you have an embedded system with scarce resources, JIT has no chance against AOT.
    However, the above was all theory. In practice, creating such an advanced JIT compiler is way more complicated than a decent AOT one. How about some practical evidence?

    source-
    Stack Overflow

    Saturday, 1 February 2014

    Display Multiple Images: Struts 2 Iterator

    This post addresses below topics
    1. Display Multiple Images using Struts 2 iterator
    2. Struts Hibernate Image Gallery
    3. Storing Image file into MySQL database through Struts Action and Hibernate.
    4. Display dynamic BLOB / byte array image on JSP using Struts 2.
    5. Convert Byte Array to Image
    6. Display image along with image content.
    7. Create a dynamic image gallery.

    This tutorial comprises of 4 Steps
    1. Read an image and store into database
    2. Get image from database using hibernate
    3. Display image on JSP dynamically
    4. Construct an Image gallery following above steps

    1. Read an image and store into database

    Below is the code example from my project where I am reading image from local directory file, then converting the image into byte array and then storing into MySQL database.

    In database you need to create a table and add a column with type BLOB or LONG BLOB to store the image byte array.
     public static void main(String[] args) throws Exception, IOException, SQLException {
        Class.forName("org.gjt.mm.mysql.Driver");
        Connection conn = DriverManager.getConnection("jdbc:mysql://IP-AddrOrHostName:Port/database-name", "user-id", "password");
        String INSERT_PICTURE = "insert into image_table(image_id, image_src, image_title) values (?, ?, ?)";
    
        FileInputStream fis = null;
        PreparedStatement ps = null;
        try {
          conn.setAutoCommit(false);
          File file = new File("C:/Ankit/workspace/image.jpg");
          fis = new FileInputStream(file);
          ps = conn.prepareStatement(INSERT_PICTURE);
          ps.setString(1, "1"); //This is image ID
          ps.setBinaryStream(2, fis, (int) file.length());
          //Or you can also use this:
          //ps.setBlob(2, fis, (int) file.length());
          ps.setString(3, "Ready for the Event?"); //This is image Title
          ps.executeUpdate();
          conn.commit();
        }
        catch(Exception ex){
         ex.printStackTrace();
        }
        finally {ps.close();
          fis.close();
        }
      }

    2. Get image from database using hibernate
     If you are working with hibernate POJOs, make sure you use a byte array field which would map to the blob column we created in step 1.
    Otherwise if you are simply working with JDBC/ODBC take out the result set output into a byte array field.
    Would post code shortly :)